Showing posts with label cloud. Show all posts

Monday, March 16, 2015

Benchmarking Postgres in the Cloud, part 1

In 2008, when Heroku started, there was only one real option for cloud hosting PostgreSQL: roll-your-own on EC2, or a couple other not-very-competitive platforms.  Since then, we've seen the number of cloud hosting providers explode, and added several "PostgreSQL-As-A-Service" providers as well: first Heroku, then Gandi, CloudFoundry, RDS, OpenShift and more.  This has led many of pgExperts' clients to ask: "Where should I be hosting my PostgreSQL?"

So to provide a definitive answer to that question, for the past several weeks I've been doing some head-to-head testing of different cloud hosting options for PostgreSQL.  Even more work has been done by my collaborator, Ruben Rudio Rey of ManageACloud.com.  I will be presenting on the results of this testing in a series of blog posts, together with a series of presentations starting at SCALE and going through pgConf NYC, LinuxFestNorthWest, and culminating at pgCon.   Each presentation will add new tests and new data.

Here's my slides from SCALE, which compare AWS, RDS, and Heroku, if you want to get some immediate data.

What We're Testing

The idea is to run benchmarks against ephemeral instances of PostgreSQL 9.3 on each cloud or service.  Our main goal is to collect performance figures, since while features and pricing are publicly available, performance information is not.  And even when the specification is the same, the actual throughput is not.  From each cloud or service, we are testing two different instance sizes:

Small: 1-2 cores, 3 to 4GB RAM, low throughput storage (compare EC2's m3.medium).  This is the "economy" instance for running PostgreSQL; it's intended to represent what people with non-critical PostgreSQL instances buy, and to answer the question of "how much performance can I get for cheap".

Large: 8-16 cores, 48 to 70GB RAM, high throughput storage (compare EC2's r3.2xlarge).  This is the maximum for a "high end" instance which we could afford to test in our test runs. 

The clouds we're testing or plan to test include:
  • AWS EC2 "roll-your-own".
  • Amazon RDS PostgreSQL
  • Heroku
  • Google Compute Engine
  • DigitalOcean
  • Rackspace Cloud
  • OpenShift PostgreSQL Cartridge
  • (maybe Joyent, not sure)
Note that in many cases we're working with the cloud vendor to achieve maximum performance results.  Our goal here isn't to "blind test" the various clouds, but rather to try to realistically deliver the best performance we can get on that platform.  In at least one case, our findings have resulted in the vendor making improvements to their cloud platform, which then allowed us to retest with better results.

The tests we're running include three pgbench runs:

  • In-Memory, Read-Write (IMRW): pgbench database 30% to 60% of the size of RAM, full transaction workload
  • In-Memory, Read-Only (IMRO): pgbench database 30% to 60% of RAM, read-only queries
  • On-Disk, Read-Write (ODRW): pgbench database 150% to 250% of RAM, full transactions
The idea here is to see the different behavior profiles with WAL-bound, CPU-bound, and storage-bound workloads.  We're also recording the load time for each database, since bulk loading behavior is useful information for each platform. 

Each combination of cloud/size/test needs to then be run at least 5 times in order to get a statistically useful sample.  As I will document later, often the difference between runs on the same cloud was greater than the difference between clouds.

Issues with pgBench as a Test Tool

One of the early things I discovered was some of the limitations of what pgbench could tell us.  Its workload is 100% random access and homogeneous one-liner queries.  It's also used extensively and automatically to test PostgreSQL performance.  As a result, we found that postgresql.conf tuning made little or no difference at all, so our original plan to test "tuned" vs. "untuned" instances went by the wayside.

We also found on public clouds that, because of the rapidfire nature of pgbench queries, performance was dominated by network response times more than anything on most workloads.  We did not use pgbench_tools, because that is concerned with automating many test runs against one host rather than a few test runs against many hosts.

For this reason, we also want to run a different, more "serious" benchmark which works out other performance areas.  To support this, I'm working on deploying Jignesh's build of DVDStore so that I can do that benchmark against the various platforms.  This will require some significant work to make a reality, though; I will need to create images or deployment tools on all of the platforms I want to test before I can do it.

To be continued ...

Sunday, February 15, 2015

Running with scissors mode

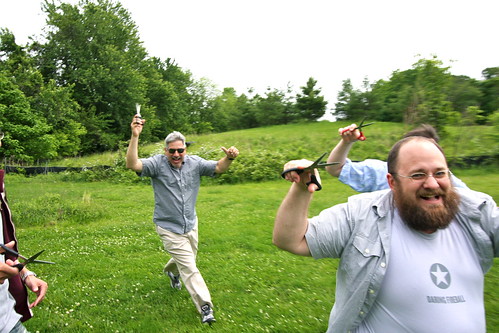
DBAs Running with Scissors

Based on some comments in my post about "in-memory" databases, I realized that my post about running Postgres without disk sync was no longer available on Database Soup.  So I'm reposting the instructions here.

This blog post version has corrections and clarifications thanks to Andres Freund, since it first went up yesterday.  Thanks, Andres.

Running PostgreSQL this way was christened "running with scissors mode" by Gavin Roy, because you're operating completely without crash-safety; if something happens to the server, even a power fluctuation, your database contents are untrustworthy and may be corrupt.  However, it can be a useful way to run Postgres for extra, read-only replicas used strictly for load-balancing, or if what you're loading into Postgres is completely disposable/replaceable.

Note that these settings do not, in fact, disable all disk writes.  What they do instead is minimize disk writes, and make all disk writes asynchronous, dependant entirely on the OS's own memory swapping and dirty block flushing for any disk writes.  This is what you want; you don't want the database to halt because, for example, you simply ran out of space in memory.

So, without further ado, here's the settings:

    work_mem =  (RAM - DBsize - shared_buffers)*2 / max_connections
    temp_buffers = (RAM - DBsize - shared_buffers)*4 / max_connections
    temp_file_limit = 0

On the one hand, we want to set work_mem high in order to avoid on-disk sorts. On the other hand, having pinned RAM for sorts push the database out of memory would be counterproductive.  As such, you want to set up work memory to use available RAM you don't need for database caching.  The above assumes that max_connections is set to something sensible for the number of connections you actually need.  You should really be using pgbouncer as well with this setup.


Set temp_file_limit = 0 to cause queries to be cancelled instead of doing disk sorts.

     bgwriter_lru_maxpages = 0
     wal_level = minimal
     fsync = off
     synchronous_commit = off
     full_page_writes = off

     wal_log_hints = off
     wal_buffers = 64MB


Here we're minimizing the amount of writing we do to the transaction log, and making said writing completely asynchronous.  We're also disabling background writing.

     checkpoint_segments = 8 to 64
   checkpoint_timeout = 60min
     checkpoint_completion_target = 0.9

Checkpoint segments is a bit trickier.  On the one hand, you want it to be large enough that it's not cycling a lot and triggering extra disk flushes. On the other hand, you want all the segments to stay cached in RAM.  So something moderate, 256MB to 2GB, depending on how much RAM you have.  Don't set it to more than 1/32nd of RAM.  Ideally, we'd be able to disable checkpoints entirely, but currently there's no reasonable way to do that.

   stats_temp_directory = '/pgramdisk/stats_tmp'

You will also want to move the stats file to a ramdisk so that it's not being written out.  This is a good optimization in general, even outside of running with scissors mode.


Finally, we need to ensure that PostgreSQL will not restart if the system crashes; at that point, you assume your database is corrupt and proceed to recover it from another source.  The first part of doing this is to disable any autostart in your init system configuration.  Secondly, after starting up Postgres, add a line like this to the beginning of postgresql.conf:

     DO_NOT_RESTART=True

The exact parameter you use doesn't matter; what matters is that it's not a recognized parameter, so that Postgres will error out instead of  restarting.  This does mean extra steps when you want to manually restart this node for configuration changes, but there isn't a really good way around that.

Next up, we'll run some performance tests to see how much this benefits us.

Continued in Part II.

Photo of "DBAs running with scissors" taken by Gavin Roy.

Thursday, November 6, 2014

We need a webapp benchmark

I've been doing some comparative testing on different cloud platform's hosting of PostgreSQL.  And one of the deficiencies in this effort is the only benchmarking tool I have is pgbench, which doesn't reflect the kinds of workloads people would want to run on cloud hosting.  Don't get me wrong, pgbench does everything you could imagine with the simple Wisconsin benchmark, including statistics and sampling.   But the core benchmark is still something which doesn't look much like the kind of Rails and Django apps I deal with on a daily basis.

There's also TPCC-js, which is more sophisticated, but is ultimately still a transactional, back-office OLTP benchmark. 

So I'm thinking of developing a "webapp" benchmark.  Here's what I see as concepts for such a benchmark:
  • Read-mostly
  • No multi-statement transactions
  • Defined "users" concept with logins and new user registration
  • Needs a "sessions" table which is frequently updated
  • Read-write, read-only and session database connections should be separable, in order to test load-balancing optimization.
  • Queries counting, sorting and modifying content
  • Measured unit of work is the "user session" which would contain some content lookups and minor updates ("likes").
Now, one of the big questions is whether we should base this benchmark on the idea of a social networking (SN) site.  I think we should; SN sites test a number of things, including locking and joins which might not be exercised by other types of applications (and aren't by pgbench).  What do you think?  Does anyone other than me want to work on this?

Monday, November 11, 2013

SFPUG November: Gandi.net and Postgres (live video)

As usual, we plan to have live video of Wednesday's San Francisco PostgreSQL User Group meeting. This one will involve Gandi.net showing off their new PostgreSQL-As-A-Service offering, as well as talking about how Gandi.net uses PostgreSQL internally to support their services. Since PostgreSQL.org uses Gandi.net to host many of our domains, it's a wonderful friendly full-circle group hug. Tune in! We're liable to start around 7:15 PM PST.

Tuesday, October 9, 2012

Postgres SMF Permissions on Joyent SmartOS

A few of our clients run on the Joyent cloud.  Uniquely, Joyent runs SmartOS, an Illumos (i.e. OpenSolaris) distribution, which is the default and supported OS on VMs.   Like Solaris 10 and 11, SmartOS controls server services using the Service Management Framework, or SMF, and XML-configuration-driven tool which supports version-specific start, stop, restart, reload and auto-vivification for PostgreSQL.

Now, for replication failover between SmartOS hosts on Joyent, one of the things we need to do is STONITH ("Shoot The Other Node In The Head") which includes shutting down Postgres on the old master if it's still running.  For various setup reasons, our scripts need to do this as the "postgres" user, not as root.  But, thanks to auto-vivification, if we just "pg_ctl stop", SMF will automatically restart PostgreSQL after a few minutes.  So we needed to grant permission for the postgres user to enable, disable and restart the PostgreSQL service.

Unfortunately, permissions on services are a wierd alchemy of SMF configuration and RBAC, the Solaris security framework.  After several hours of struggling with how to do this, Joyent support came to the rescue.  Ryan Puckett gave me this formula:

echo "postgres.applications:::Manage Postgres::" >> /etc/security/auth_attr
echo "postgres::::type=normal;auths=postgres.applications" >> /etc/user_attr
svccfg -s postgresql setprop general/action_authorization = astring: postgres.applications
svccfg -s postgresql setprop general/value_authorization = astring: postgres.applications 
 
And I'm delighted to report that, after running the above commands, the postgres user can run "/usr/sbin/svcadm disable postgresql".   Yay!

Monday, May 7, 2012

Amazonstravaganza tommorrow, on UStream

Tommorrow we're going to have two back-to-back SFPUG presentations about running PostgreSQL on AWS: Scalr presenting their stuff, and "Amazon With Reduced Tears" by Christophe Pettus.  The event is sold out at 100 RSVPs, though, so I suggest you watch it on video!

Barring severe technical difficulties, it will be presented live on SFPUG Ustream.   Festivities should start around 7:15 PM PDT.

Tuesday, March 27, 2012

PostgreSQL needs a new load balancer

We do a lot of high-availablity PostgreSQL deployments for clients.  As of 9.1, streaming replication (SR) is excellent for this, and can scale sufficiently to scale a client across and AWS node cluster with some simple tools to help manage it.  But where we're keenly feeling the lack is simple load balancing and failover.

We use pgPool a lot for this, and once you've set it up it works.  But pgPool suffers from runaway sporkism: it's a load balancer and a failover tool and multimaster replication and data partitioning and a cache and compatible with SR and Slony and Bucardo.  If you need all of those things, it's great, but if you only need one of them you still get the complexity of all of them.  It also suffers from having been designed around the needs of specific SRA customers, and not really for general use.  We've been tinkering with it for a while, and I just don't see a way to "fix" pgPool for the general use case; we need something new, designed to be simple and limited to the 80% use-case from scratch.

What we really need is simple tool, or rather a pair of tools, designed to only do failover and read load-balancing, and only for PostgreSQL streaming replication.  These tools should be stackable in any combination the user wants, like pgBouncer (and, for that matter, with pgBouncer).  They should provide information via a web service, and be configurable via a web service.

I'll call the first tool "pgFailover".  The purpose of this tool is to manage a master-replica group of servers, including managing both planned and unplanned failovers.  You would only have one active pgFailover node within a group in order to avoid "split-brain" issues.  It will not handle database connections at all.

pgFailover would track a master and several replicas.  The status of each server would be monitored by polling both the replication information on each server, and pg_stat_replication on the master.  This information would be provided to the network by pgFailover via a web service, and pgFailover would accept commands via the same webservice as well as on the local command line.

Based on user-configurable criterial, pgFailover would carry out any of the following operations: failover to a new master; remaster the other replicas; add a new replica, with or without data sync; resync a replica; or shut down a replica.  It would also handle some situations automatically.  In the event that user-configurable conditions of nonresponsiveness are met, it would fail over the master to the "best" replica. The failover replica would be decided based on either the configuration or based on which replica is most caught up according to replication timestamps.  Likewise, replicas would be dropped from the availability list if they stop replicating for a certain period or become nonresponsive. 

The second tool I'll call "pgBalancer", after the unreleased tool from Skype.  pgBalancer would just do load-balancing of database connections across the replicated servers.  It won't deal with failover or monitoring the servers at all; instead, it relies entirely on pgFailover for that.  This allows users to have several separate pgBalancer servers, supporting both high availabilty and complex load-balancing configurations.

Since automated separation of read and write queries is an impossible problem, we won't even try to solve it.  Instead, we'll rely on the idea that the application knows whether it's reading or writing, and provide two separate database connection ports, one for read-write (RW) connections, and one for read-only (RO) connections.  pgBalancer would obtain information on what servers to connect to by either a configuration file, or by querying a pgFailover server for information via its web service.  RO connections would be load-balanced across available servers, based on a simple "least active" plus "round-robin" algorithm.

pgBalancer would also accept a variety of commands via web service, including: suspend a service or all services; disconnect a specific connection or all connections; failover the write node to specific new server; drop a server from the load balancing list; add a server to the load balancing list; give a list of connections; give a list of servers.

If we could build two tools which more-or-less match the specification above, I think they would go a lot further towards supporting the kinds of high-availability, horizontally-scaled PostgreSQL server clusters we want to use for the applications of the future. Time permitting, I'll start work on pgFailover.  A geek can dream, can't he?